Mutex or channel in Go? Measured under contention
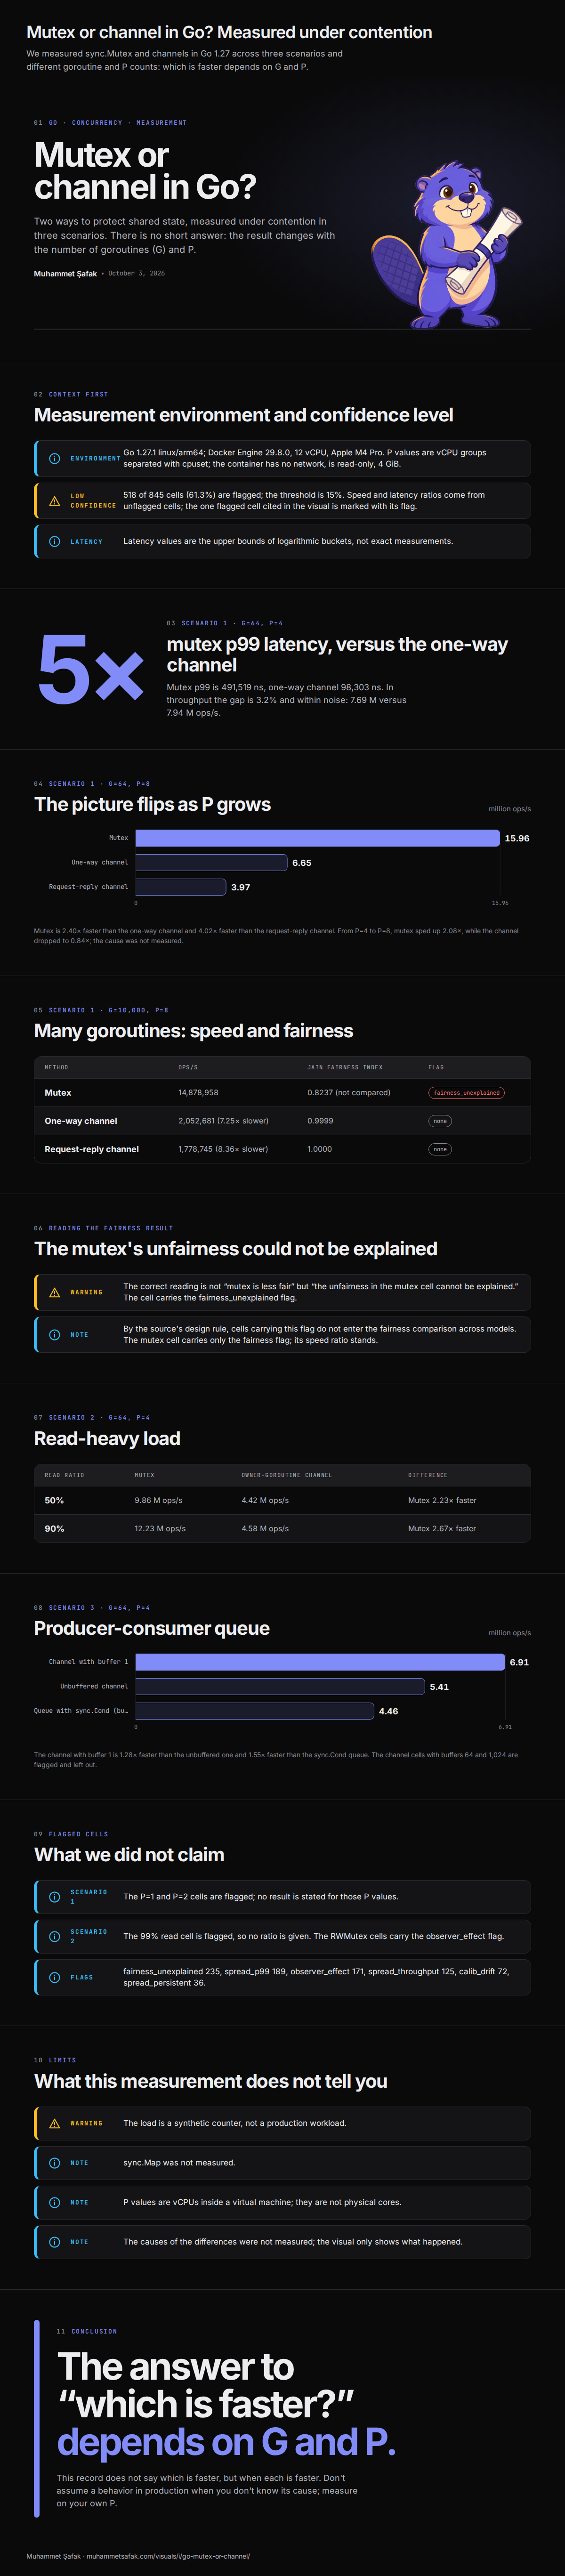
We measured sync.Mutex and channels in Go 1.27 across three scenarios and different goroutine and P counts: which is faster depends on G and P.
Go · Concurrency · Measurement
Mutex or channel in Go?
Two ways to protect shared state, measured under contention in three scenarios. There is no short answer: the result changes with the number of goroutines (G) and P.
Context first
Measurement environment and confidence level
- EnvironmentGo 1.27.1 linux/arm64; Docker Engine 29.8.0, 12 vCPU, Apple M4 Pro. P values are vCPU groups separated with cpuset; the container has no network, is read-only, 4 GiB.
- Low confidence518 of 845 cells (61.3%) are flagged; the threshold is 15%. Speed and latency ratios come from unflagged cells; the one flagged cell cited in the visual is marked with its flag.
- LatencyLatency values are the upper bounds of logarithmic buckets, not exact measurements.
5×
Scenario 1 · G=64, P=4
mutex p99 latency, versus the one-way channel
Mutex p99 is 491,519 ns, one-way channel 98,303 ns. In throughput the gap is 3.2% and within noise: 7.69 M versus 7.94 M ops/s.
Scenario 1 · G=64, P=8
The picture flips as P grows
million ops/s
- Mutex15.96
- One-way channel6.65
- Request-reply channel3.97
Scenario 1 · G=10,000, P=8
Many goroutines: speed and fairness
| Method | Ops/s | Jain fairness index | Flag |
|---|---|---|---|
| Mutex | 14,878,958 | 0.8237 (not compared) | fairness_unexplained |
| One-way channel | 2,052,681 (7.25× slower) | 0.9999 | none |
| Request-reply channel | 1,778,745 (8.36× slower) | 1.0000 | none |
Reading the fairness result
The mutex's unfairness could not be explained
- WarningThe correct reading is not “mutex is less fair” but “the unfairness in the mutex cell cannot be explained.” The cell carries the fairness_unexplained flag.
- NoteBy the source's design rule, cells carrying this flag do not enter the fairness comparison across models. The mutex cell carries only the fairness flag; its speed ratio stands.
Scenario 2 · G=64, P=4
Read-heavy load
| Read ratio | Mutex | Owner-goroutine channel | Difference |
|---|---|---|---|
| 50% | 9.86 M ops/s | 4.42 M ops/s | Mutex 2.23× faster |
| 90% | 12.23 M ops/s | 4.58 M ops/s | Mutex 2.67× faster |
Scenario 3 · G=64, P=4
Producer-consumer queue
million ops/s
- Channel with buffer 16.91
- Unbuffered channel5.41
- Queue with sync.Cond (buffer 1,024)4.46
Flagged cells
What we did not claim
- Scenario 1The P=1 and P=2 cells are flagged; no result is stated for those P values.
- Scenario 2The 99% read cell is flagged, so no ratio is given. The RWMutex cells carry the observer_effect flag.
- Flagsfairness_unexplained 235, spread_p99 189, observer_effect 171, spread_throughput 125, calib_drift 72, spread_persistent 36.
Limits
What this measurement does not tell you
- WarningThe load is a synthetic counter, not a production workload.
- Notesync.Map was not measured.
- NoteP values are vCPUs inside a virtual machine; they are not physical cores.
- NoteThe causes of the differences were not measured; the visual only shows what happened.
Conclusion
The answer to “which is faster?” depends on G and P.
This record does not say which is faster, but when each is faster. Don't assume a behavior in production when you don't know its cause; measure on your own P.