Serving the documentation of dozens of projects from one server
Build notes on serving the documentation of many projects from one multi-tenant server, each with its own MCP endpoint and documents kept on your machine.
What it does today
Makes a project's folder, git repository, Obsidian vault or Notion workspace searchable behind a single MCP endpoint, so an agent reaches the documentation without the data going to a third party. Anyone who can run Docker can host it and manage it from the dashboard.
- Started
- August 2026 — September 2026
- Left Labs
Form
Technologies
This one became a product:
ContextatorGiving a coding agent a project’s documentation runs through MCP. The protocol is not the hard part; setting the same thing up again for every project is.
One server per project, maintenance per project
For the first three projects, one MCP server each looked reasonable. Then the servers started living apart: which one indexed which directory, which had last synced, which carried its own chunking code. Every new project meant writing the same chunker, the same embedding loop and the same incremental indexer once more — and then maintaining all of them.
Contextator collapses that repetition into one installation. A project is the
sum of its sources: a folder mounted on the server, a git repository (or a
single subdirectory of it), an uploaded archive, an Obsidian vault or a Notion
workspace. They meet at one endpoint, and every source is mounted under its own
name, so a document reads as handbook/install.md.
Isolation is not a setting, it is the address
Each project gets its own URL: /mcp/<project>. A client connected to
/mcp/billing never sees /mcp/mobile.
The alternative was one endpoint with a project argument, and in that design
isolation would depend on the agent passing the right one. The cost is plain and
accepted: there is no cross-project search. One question cannot reach two
projects, because if it could, every search would silently span all of them.
Running without a key was a condition
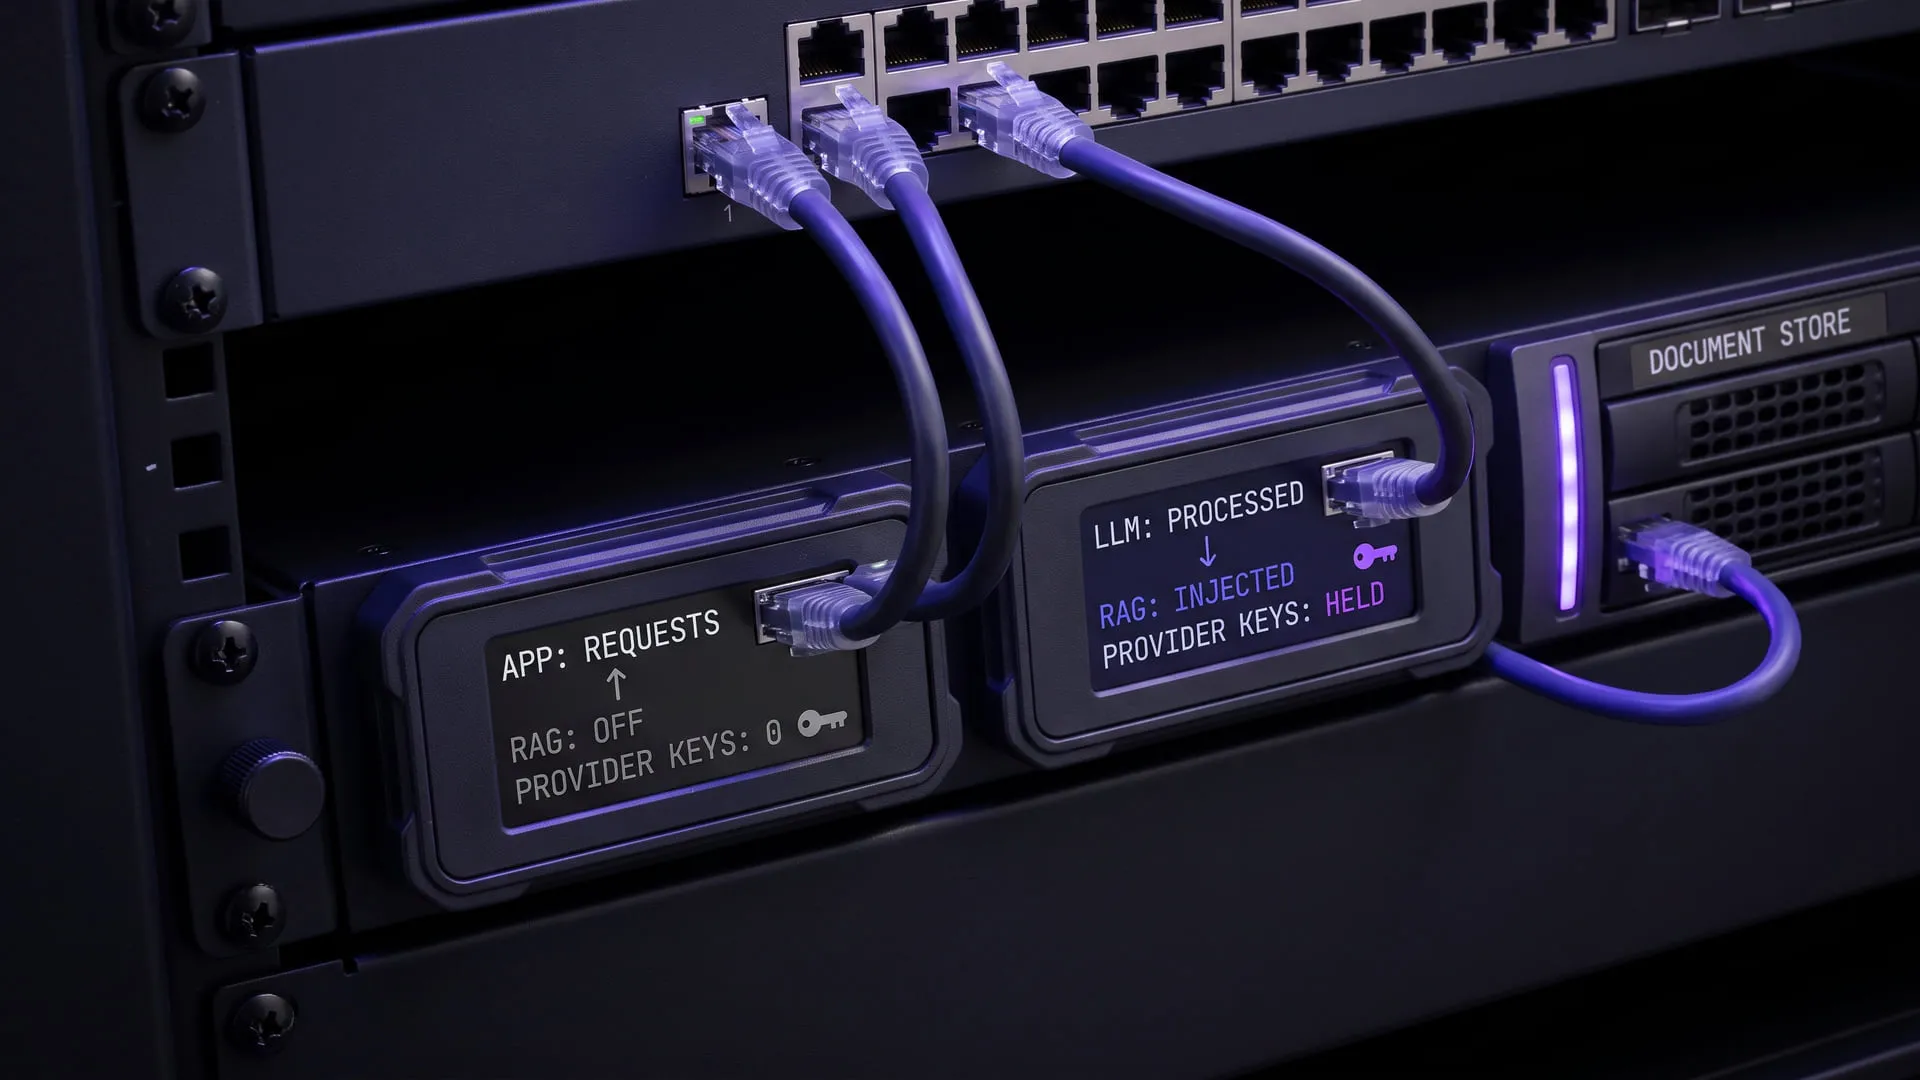
Embeddings are generated on the machine’s own CPU by default. The reason comes before cost: when a tool built to be queried constantly asks for an API key in order to work at all, it breaks the “runs on your own server” promise at the outset. A few environment variables switch it to OpenAI embeddings, but the default path never leaves the host.
The cost is paid at first start: the model is downloaded and the container takes a few minutes to come up. Later starts take seconds.
What a vector does not represent
A sentence model has no representation of HALYARD_DISPATCH_TIMEOUT — it has a
representation of the words around it. And a good share of what people search
documentation for is exactly that: a constant name, an error code, a flag.
So every chunk sits in a full-text index as well as a vector one, and a search takes both lists and fuses their rankings. Ranks are fused rather than scores, because any weighting of scores would have to be re-learnt every time the embedding model changed.
The visible cost: the similarity score on a result no longer explains why that result is where it is.
A limit that was measured and then left alone
Cross-lingual search does not work: a question asked in Turkish whose answer lives on an English page mostly goes unanswered. That is not an omission but a closed decision. Two remedies were tried: hybrid search first, then a multilingual reranking model. Both were measured, neither was enough, and the numbers are in the repository. The real fix is a second translation-trained encoder: four times the download and a full re-index on every installation. For a documentation server that price was not paid.
So the finding sits in the documentation rather than on a roadmap. The product itself is in the portfolio.